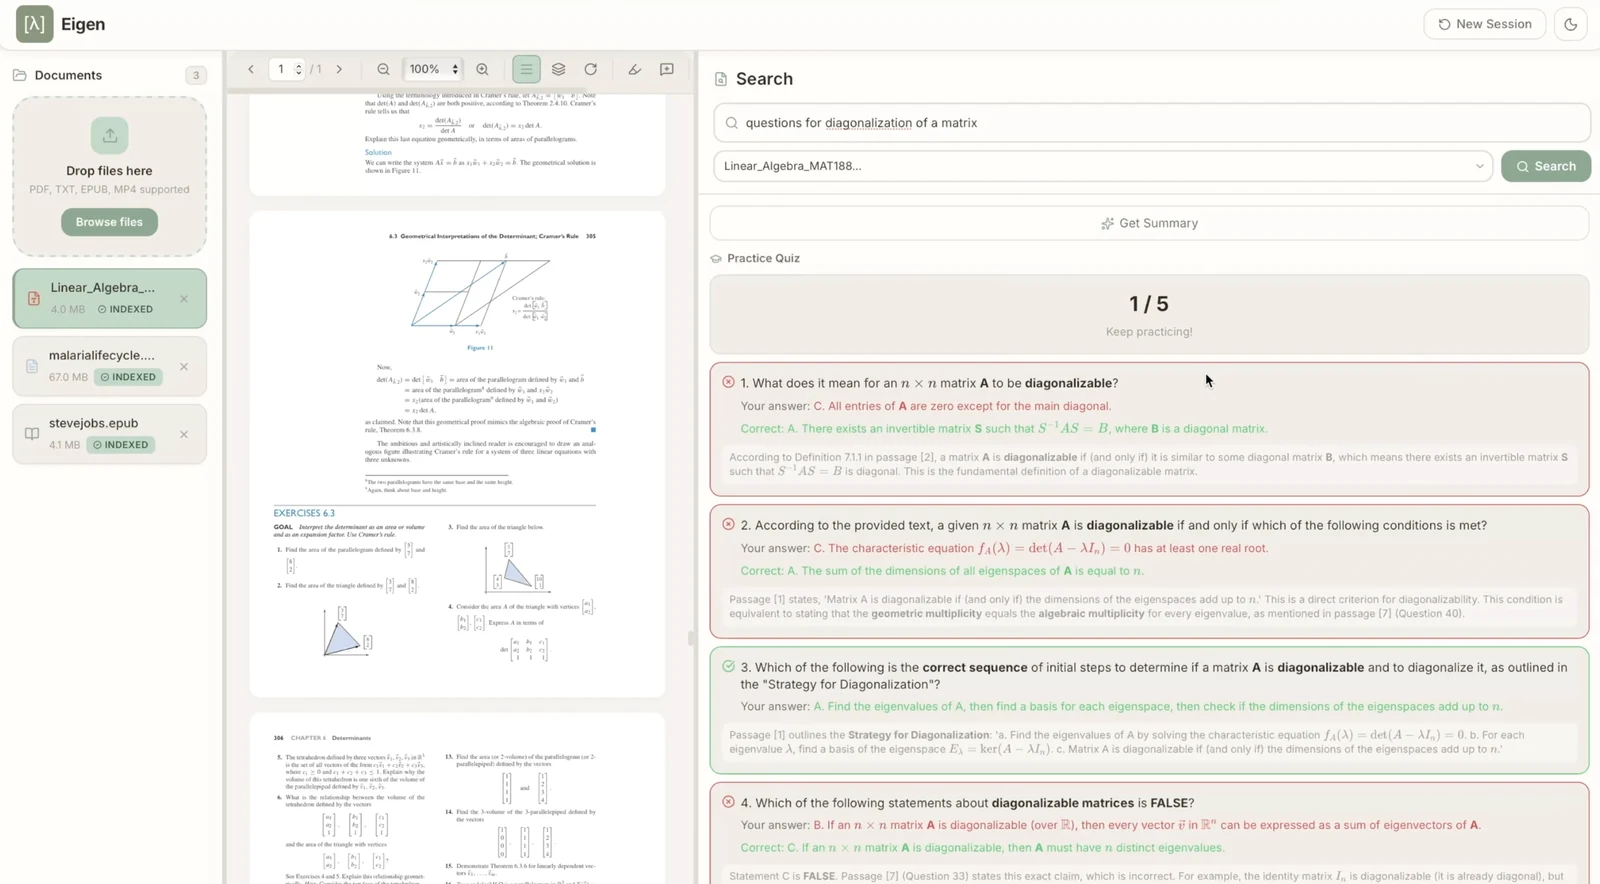
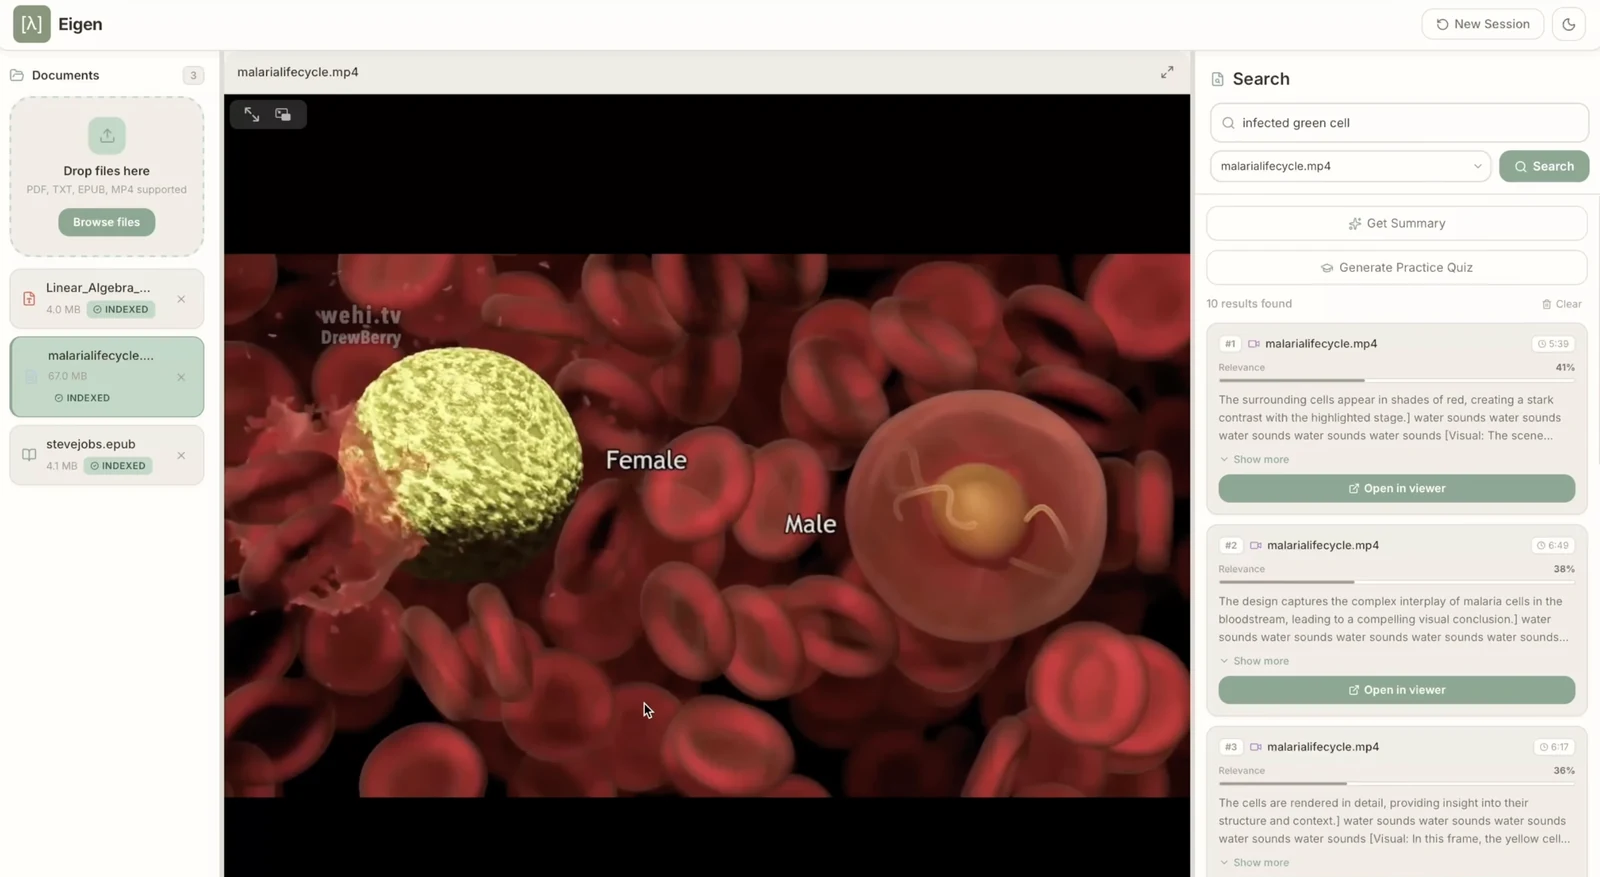
What it is:
Eigen is a study tool my team built at GenAI Genesis 2025. When you're studying, the material is usually scattered across textbooks, lecture slides and recorded videos, and finding the one spot that explains a concept means digging through all of them. Eigen lets you upload everything into one place and search it by meaning instead of exact keywords.
Searching "how do cells make energy" will find the right page of a PDF, the right chapter of an EPUB, or the exact timestamp in a lecture video, even if none of them use those words. From any result, Eigen can also generate a summary or a practice quiz on that topic.
How it works:
- Upload: Files go to a FastAPI backend, which pulls the text out of each one. PDFs and EPUBs are read directly, and videos are transcribed with Whisper so the spoken lecture becomes searchable text.
- Chunk and embed: The text is split into small overlapping chunks, and each chunk is turned into an embedding (a list of numbers that captures its meaning) using OpenAI's embedding model.
- Store: The embeddings are saved in ChromaDB, a vector database, along with where each chunk came from (page number, chapter or video timestamp).
- Search: A search query is embedded the same way, and ChromaDB returns the chunks whose meaning is closest to it. The React frontend opens the result right at that page or timestamp.
- Summarize and quiz: The matching chunks are sent to Google Gemini, which writes a summary or a set of practice questions, with LaTeX support for math.
My part was mostly the backend and AI features: I rebuilt the search pipeline around Railtracks (hackathon sponsor) and ChromaDB, added the Gemini summaries and quizzes, and built the note-taking and highlighting features in the document viewer.
What I learned:
- I learned how semantic search works: embeddings, vector databases, and why chunk size and overlap make a big difference to result quality.
- I learned how to work with LLM APIs, including writing system prompts to get Gemini to return consistently formatted summaries and quizzes.